Table of contents
Across attics and shoeboxes, analogue family photos are being pulled back into the present, not just as nostalgia but as usable data, and the shift is accelerating as consumers digitise archives at scale. In the UK and across Europe, households are scanning prints to safeguard them from fading, floods and fires, and institutions are racing to preserve collections before chemical decay makes them unreadable. Yet the real change sits beyond preservation: once an image becomes a file, it can be indexed, searched and interpreted, turning pixels into narratives people can actually retrieve.
Why everyone is scanning now
Old photos are fragile, and time is not their ally. Colour prints from the 1970s and 1980s are especially prone to fading as dye layers break down, while adhesive albums and “magnetic” pages can accelerate deterioration and leave images stuck to plastic. Add the everyday risks, including house moves, damp storage, burst pipes and the growing frequency of extreme weather events, and the rationale for digitising shifts from “nice to have” to “necessary”. Consumer behaviour reflects that urgency: the global photo printing market is mature, but the digitisation and cloud-storage ecosystem around personal media keeps expanding, fuelled by smartphones, affordable scanners and subscription storage.
The numbers tell part of the story. Billions of photographs were taken on film in the 20th century, and while exact counts vary, Kodak famously estimated in the 2010s that humans had taken well over a trillion photos in total, with a large share captured after the rise of digital. That leaves an enormous analogue residue: family albums, slides, negatives and institutional archives that are still not digitised. Museums and libraries have been sounding the alarm for years, noting that acetate film can suffer from “vinegar syndrome”, a chemical decay that warps and shrinks film, and once it starts, it can spread in storage. For households, the warning is simpler and more immediate: once a print cracks, moulds or fades, no amount of software can reconstruct what never got captured.
There is also a cultural push, and it is not confined to heritage institutions. Genealogy platforms have turned family history into a mainstream hobby, and social networks have made “memory content” a repeatable format, from anniversary posts to “then and now” threads. In that context, scanning is no longer a solitary weekend chore, it is a way to produce shareable, searchable material. The step from a paper photo to a tagged digital file changes the economics of attention: people spend time on what they can find, and they can only find what has been digitised and described.
From shoebox chaos to searchable archives
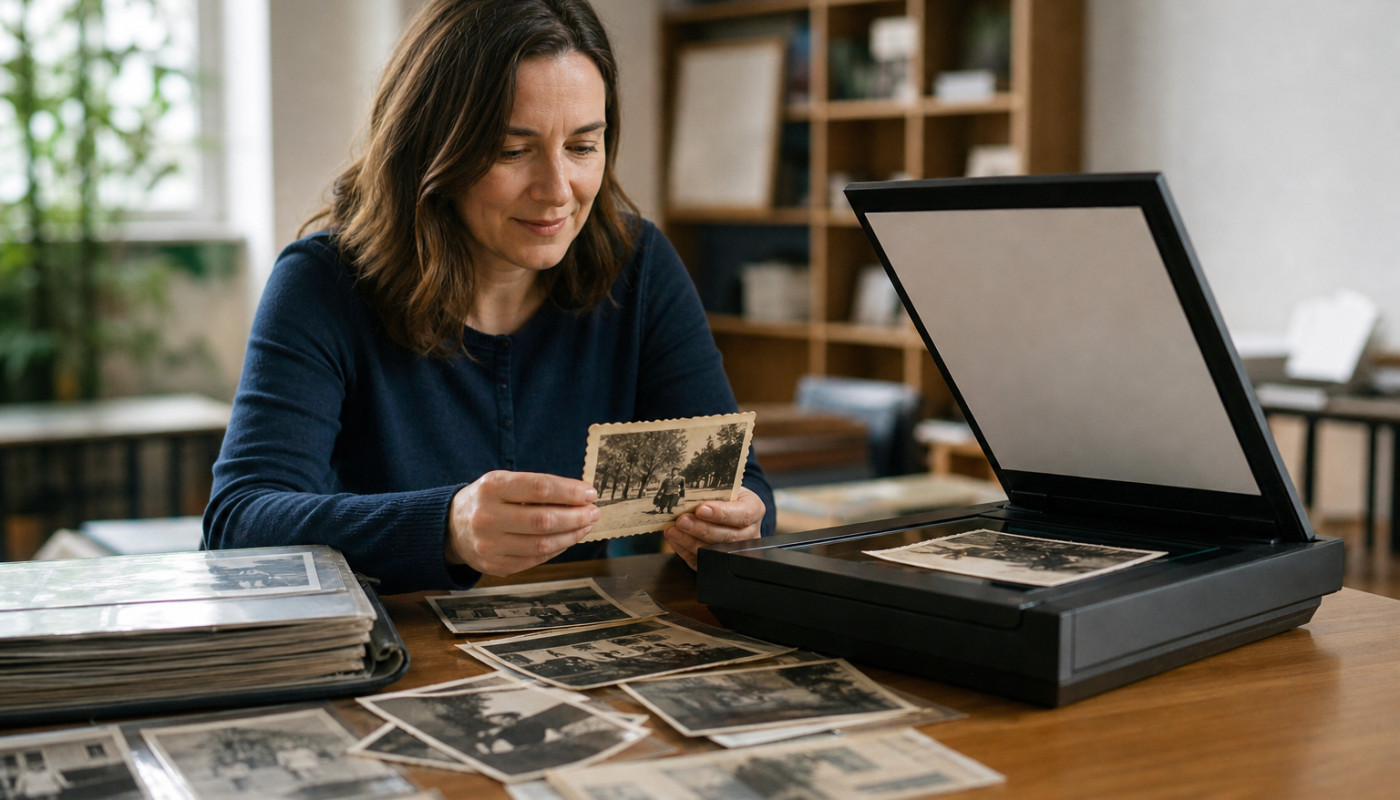
A scanned photo is not automatically an archive. The moment many people realise this is when they hit the second folder called “Scan_001” and the promise of order collapses. What separates a usable collection from a digital attic is structure: consistent file naming, basic metadata, and a strategy for duplicates. Professionals typically recommend scanning at 300 dpi for standard prints to preserve detail for viewing and reprints, and higher resolutions, often 2400 dpi or more, for negatives and slides where the source holds far more information than a paper print. File formats matter too: TIFF remains a preservation standard for lossless storage, while high-quality JPEGs are practical for everyday sharing because they are smaller and widely compatible.
Yet the real leap comes when images become searchable by more than date. Faces, locations, objects and even text on signs can be detected and indexed, and that is where modern photo management starts to look less like storage and more like a database. If a collection can answer simple questions, such as “show me every photo with my grandmother” or “find holidays by the sea”, it becomes a living resource rather than a static backup. This is the logic behind the growth of AI-driven organisation tools that treat personal media as information, not just files. For readers curious about how that shift works at a technical level, the clearest entry point is home, which lays out how AI can turn everyday content into structured, retrievable knowledge.
Importantly, searchability is not just convenience, it is also a defence against loss. When a family scans thousands of photos, the risk is not only that files disappear, but that stories do. Without context, an image becomes anonymous quickly: a child’s birthday with no names, a wedding with no date, a street with no location. Even minimal metadata, a year range, a city, a handful of names, can preserve meaning. That work is time-consuming, but it scales better than many expect: starting with broad labels, then refining the most valuable albums first, often beats attempting perfect descriptions from day one.
AI is rewriting what a photo “contains”
A photo used to be evidence, and now it is also input. Once digitised, images can be analysed for far more than what the photographer intended, and the implications are both exciting and unsettling. On the practical side, computer vision can identify faces across decades, group images by event, detect landmarks, read handwritten notes on the back of prints, and even estimate time periods based on clothing, cars or film characteristics. That turns a pile of unlabelled pictures into something closer to a chronological narrative, and it can surface connections that families have forgotten, such as recurring people at gatherings or trips that span years.
For institutions, the promise is even bigger. Archives sit on massive backlogs: millions of images that are catalogued only at collection level because item-by-item description is expensive. AI-assisted tagging and transcription can speed up access, and access is often the bottleneck for funding and public engagement. When collections become searchable, they become usable by researchers, journalists and communities, and that can reshape what gets written into the public record. The risk, however, is that automated interpretation introduces bias, misidentifies people, or overconfidently labels uncertain details. Responsible workflows treat AI output as a draft, not a verdict, and they keep provenance clear: what is known, what is inferred, and what remains unknown.
For families, the ethical questions are more intimate. Face recognition makes it easier to organise, but it also raises privacy concerns, especially if processing happens in the cloud or if accounts are shared across relatives. The safest approach is to be explicit about consent when living people are involved, and to pay attention to where files are stored, how they are encrypted, and who can access them. Practical steps matter: using local processing when possible, enabling two-factor authentication, and separating “share” folders from the master archive reduces the chance that a private history becomes public by accident. AI can deliver extraordinary recall, but it also demands a higher standard of stewardship.
How to digitise without wasting money
The scanning market can feel like a trap: buy the wrong device, and you will either spend too much or give up halfway. The right choice depends on volume and format. Flatbed scanners are versatile for prints and documents, and good models handle gentle photo scanning without damaging originals. Dedicated photo scanners can be faster for stacks of prints, and film scanners are often essential for negatives and slides if you want high-resolution results. Outsourcing is the fastest route for large collections, particularly when time matters more than total cost, but quality varies, and readers should ask what resolution is delivered, whether colour correction is applied, and how the files are returned and backed up.
Budgeting is easier when you break the job into stages. Start with triage: identify the most at-risk items, such as curled prints, fading colour photos, and fragile albums, and digitise those first. Next, prioritise the most meaningful sets, weddings, childhood years, family members who have passed away, because the value of retrieval is highest there. Finally, tackle the long tail. This approach keeps motivation up and avoids paying to scan hundreds of near-duplicates. It also allows for a sensible quality ladder: high resolution and lossless formats for irreplaceable originals, and more compact settings for less critical material.
People often forget the ongoing costs. Storage is cheap until it is not: multiple backups, ideally in at least two locations, are the real price of preservation. A practical rule is to keep three copies, on two different media, with one stored off-site. Cloud subscriptions add up, but they also protect against local disasters, and the best plans include versioning so accidental deletions can be reversed. For readers in Europe, it is also worth checking whether local libraries, community heritage projects or municipal archives offer digitisation support or scanning stations; such initiatives exist in many cities, and they can cut costs while providing guidance on preservation standards.
Booking, costs and help available
Plan a realistic schedule, and scan in batches. For a DIY route, expect equipment from roughly £100 to £400, then ongoing storage costs. For large volumes, request quotes, and confirm resolution, formats and turnaround. Look for local libraries and community heritage programmes, which sometimes provide scanners, workshops and advice at low cost.
Similar articles